What is RLHF in AI?
Quick answer
RLHF, reinforcement learning from human feedback, is a training step where people compare or rate a model's answers and the model is adjusted to give more of the answers people preferred. It is a big part of how a raw text predictor becomes a helpful, polite assistant that follows instructions.
Last updated
Take the free module →Module 5 of the free Better Prompts course, about 6 minutes. No account needed.
Updated · By Robert Breen
Why it matters for a small business
OpenAI described using RLHF for InstructGPT in 2022 and for ChatGPT. Other labs use related methods; Anthropic, for example, has published its Constitutional AI approach, which uses written principles and AI feedback as well as human ratings.
For you, RLHF explains the assistant's default personality: careful, positive, thorough and a little generic. That style is what raters tended to prefer on average. When you want a different voice, shorter answers or your own phrases, you have to ask for it, ideally by showing examples.
Preference training can also make a model too eager to please, a problem called sycophancy. That is one more reason to ask for weaknesses and to check facts yourself rather than reading agreement as confirmation.
In a real lesson: Give Examples: Few-Shot Prompts That Copy Your Style
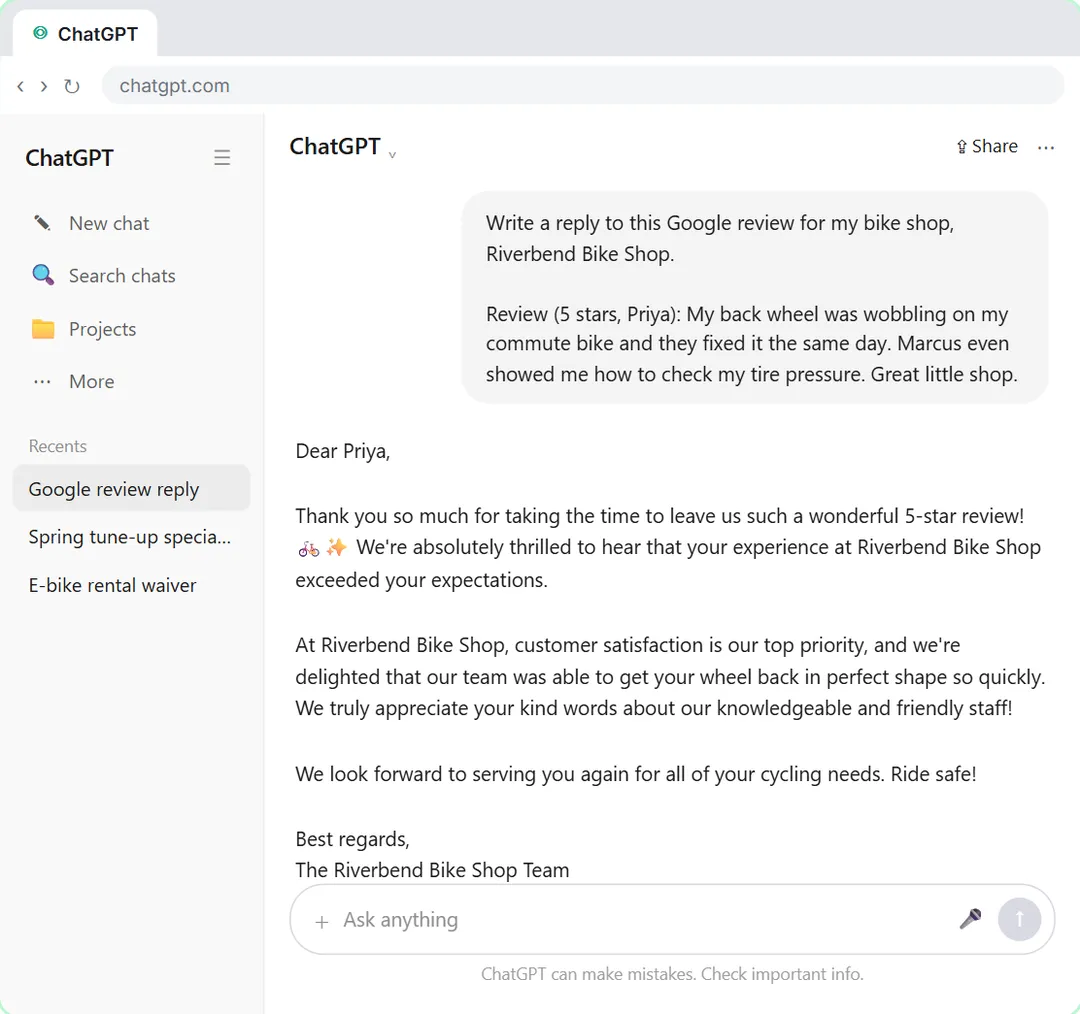
In Give Examples: Few-Shot Prompts That Copy Your Style, a bike shop owner asks ChatGPT for a Google review reply with no examples and gets the usual corporate thank-you. That polished, safe default is the kind of answer preference training rewards.
Then he pastes three of his own past replies and asks again. The new reply sounds like him. The training didn't change; the examples in the prompt gave the model a clearer target than its default.
Try this lesson free or read the step-by-step guide.
Common confusions
RLHF vs the thumbs-up button
Thumbs up and down in a chat app are feedback a company may use later. RLHF is the training process itself, run by the AI company.
RLHF vs fine-tuning
RLHF is one kind of fine-tuning, based on preferences. Fine-tuning can also mean training on example answers directly.
Tips
- If the tone is too corporate, show two or three real examples of your own writing.
- Ask for "no filler" and a word limit to cut the default padding.
- Don't read politeness as accuracy; check facts either way.
Related terms
More AI basics terms
Where you use it: free lessons
- Give Examples: Few-Shot Prompts That Copy Your Style (ChatGPT, 6 min)
- Catch Made-up Facts Before They Reach Customers using ChatGPT (ChatGPT, 7 min)
Frequently asked questions
- Is RLHF why ChatGPT is so polite?
- It is a large part of it. Raters tended to prefer polite, helpful answers, so the model learned to give them.
- Do I do RLHF when I rate an answer?
- Not directly. Your rating is feedback the company may use in future training, depending on your data settings.
- Does RLHF make AI more accurate?
- It makes answers more helpful and better behaved, but it doesn't guarantee facts. Check anything that matters.