What is chunk overlap in RAG?
Quick answer
Chunk overlap is the number of characters or tokens that two neighboring chunks share when a document is cut up for AI search. The end of one chunk is repeated at the start of the next. That way a rule split across a chunk boundary still appears complete in at least one of them.
Last updated
Take the free module →Module 15 of the free AI for Customer Support course, about 14 minutes. No account needed.
Updated · By Robert Breen
Why it matters for a small business
Before a chatbot can search a handbook, the handbook is cut into chunks of a set size. A cut falls wherever the size runs out, and sometimes that is in the middle of the one sentence that answers a question. With no overlap, half the rule sits at the end of one chunk and half at the start of the next, and neither half is a good match on its own.
Overlap is the cheap fix. Repeating a short stretch of text at each boundary means the full sentence shows up somewhere. The price is a little extra storage and some repeated text in search results. A common starting point is an overlap of about 10 to 20 percent of the chunk size, then you adjust it after testing real questions.
In a real lesson: Make Your Handbook Searchable for an AI Helpdesk using Pinecone + n8n
In Make Your Handbook Searchable, you add a Recursive Character Text Splitter under the Default Data Loader. Chunk Size is 1000 characters, about a long paragraph, and you set Chunk Overlap to 200. The voiceover gives the reason in one line: a sentence that crosses two chunks shows up in both.
When you click Execute workflow, the Cedar Ridge employee handbook becomes 38 chunks in Pinecone. Because each chunk shares 200 characters with its neighbor, a policy such as the home office furniture allowance is less likely to be split so badly that the chatbot in the next lesson can't find it.
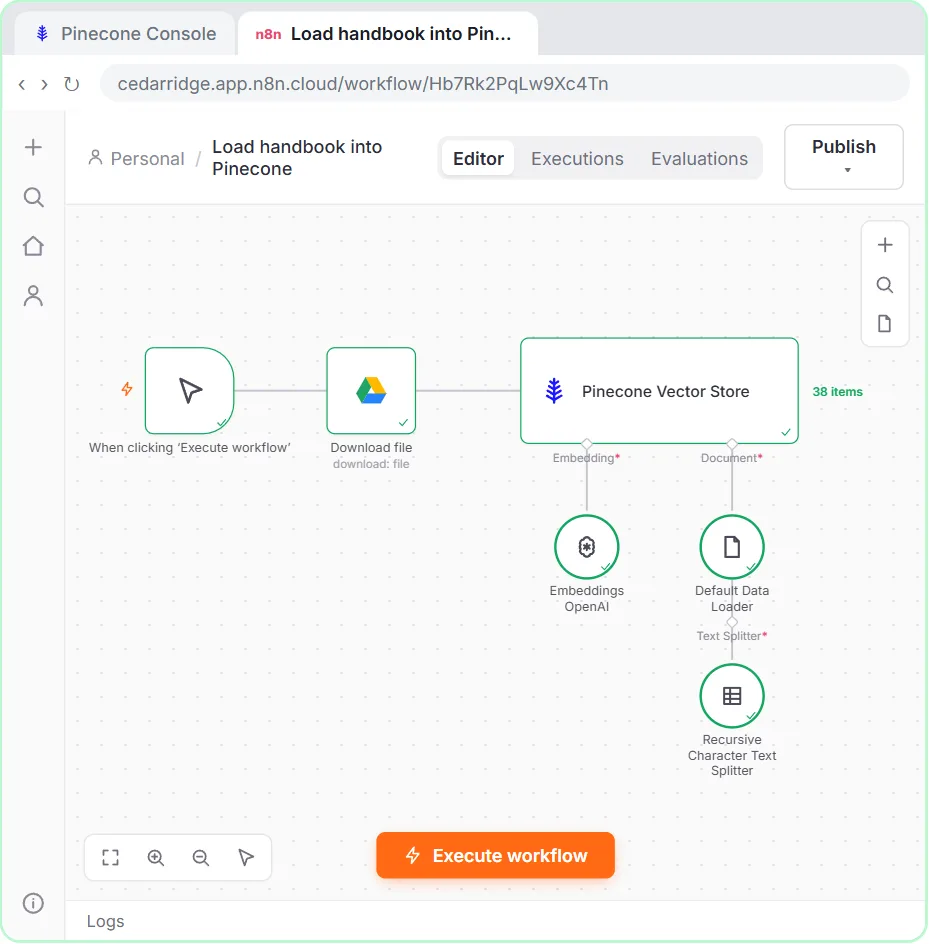
Try this lesson free or read the step-by-step guide.
Common confusions
Chunk overlap vs chunk size
Chunk size is how long each piece is. Overlap is how much of that length is shared with the next piece. Overlap must be smaller than the size.
Chunk overlap vs duplicate records
Overlap repeats a few lines on purpose. Loading the same file twice without clearing the namespace stores every chunk twice, which is a mistake.
Tips
- Start with an overlap around a fifth of your chunk size, such as 200 for 1000.
- Test questions whose answers sit near a page or section break, then adjust.
- Keep the same chunk settings when you reload a document, so old and new results behave the same.
Related terms
More AI basics terms
Where you use it: free lessons
Frequently asked questions
- Is more overlap always better?
- No. Too much overlap stores lots of repeated text and can return near-identical chunks for one question, which crowds out other useful results.
- Is overlap counted in characters or tokens?
- It depends on the splitter. n8n's Recursive Character Text Splitter counts characters; a token-based splitter counts tokens.
- Do tools like Custom GPTs let me set overlap?
- Usually not. Hosted tools pick chunk settings for you. You set them yourself when you build the pipeline, as in n8n.