What is an AI benchmark?
Quick answer
An AI benchmark is a fixed set of test questions or tasks used to score and compare AI models, such as exam-style questions across many subjects, real coding problems or hard reasoning puzzles. Labs publish benchmark scores when they release a model, and leaderboards rank models by them.
Last updated
Take the free module →Module 2 of the free Claude Jump Start course, about 7 minutes. No account needed.
Updated · By Robert Breen
Why it matters for a small business
Benchmarks are useful for spotting which models are near the top. Well-known examples include MMLU (multiple-choice questions across dozens of subjects) and SWE-bench (fixing real software issues). They are less useful for choosing a tool for your office work, because none of them is your customer email, your contract or your spreadsheet.
Scores can also mislead. Popular benchmarks saturate as top models all score near the maximum, and test questions can leak into training data. Treat a benchmark as a shortlist, then run your own small test.
Leaderboards where people vote on answers side by side, rather than fixed test sets, are another popular way to compare models. They reflect what many users prefer, which still may not be what your clients need.
In a real lesson: Your First Chat with Claude: Models, Files and a Great First Prompt
In Your First Chat with Claude, the model picker doesn't show any benchmark scores. It describes each model by its job: Fable for the toughest challenges, Opus for complex and everyday work, Sonnet for simpler tasks, Haiku for quick answers.
The lesson then tests a model on a real task, the reply to Linda's patio complaint, and checks names, dates, prices and promises. That is your own benchmark: the same real task, run on the models you're choosing between, scored on what matters to you.
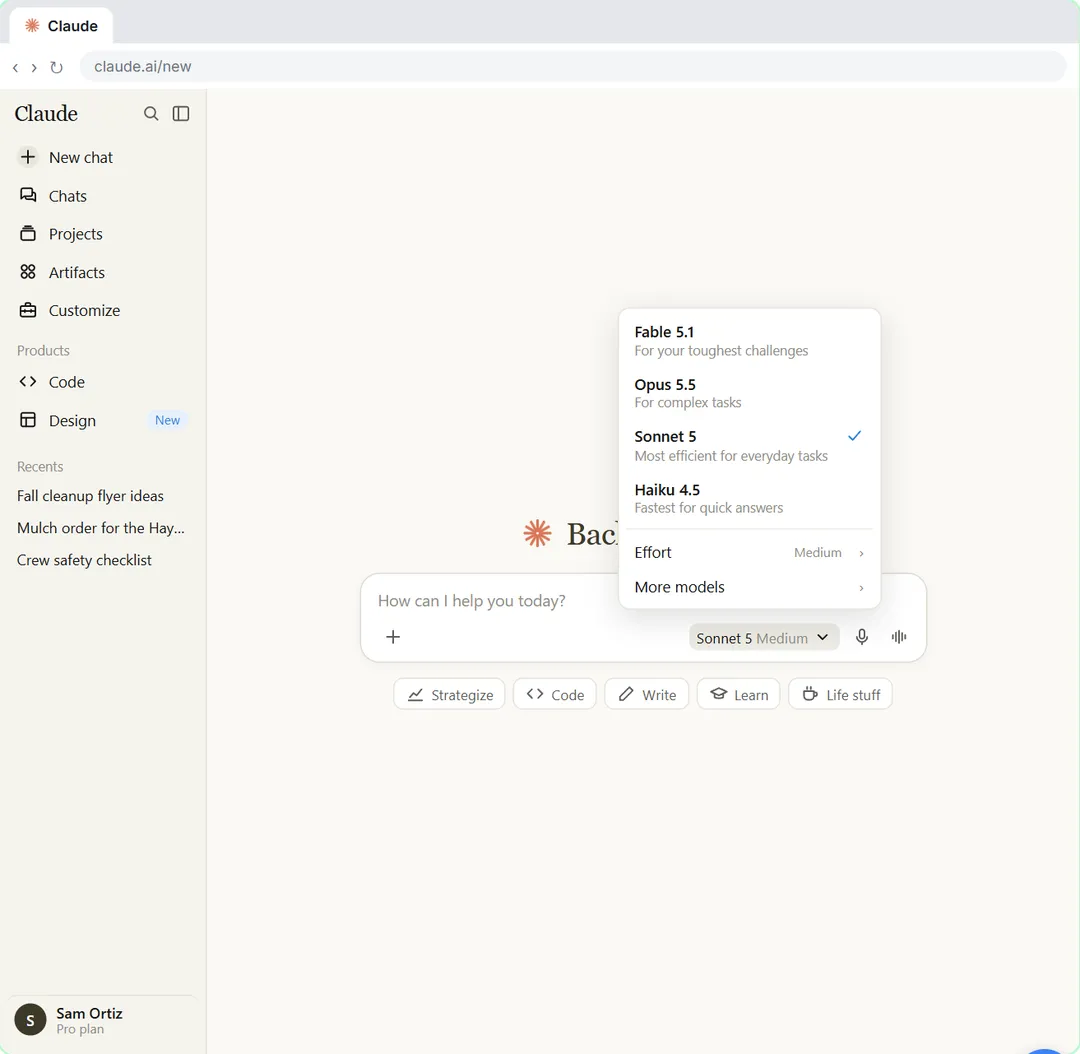
Try this lesson free or read the step-by-step guide.
Common confusions
Benchmark vs evals
A benchmark is a public, standard test. Evals are tests you build from your own tasks to check a prompt or tool you rely on.
Benchmark vs leaderboard
A leaderboard ranks models, often across several benchmarks or by people voting on answers. It is a summary, not a test of your work.
Tips
- Use benchmarks to shortlist two or three models, not to pick one.
- Test the shortlist on three to five of your real tasks.
- Check price and speed alongside quality.
Related terms
More AI basics terms
Where you use it: free lessons
- Your First Chat with Claude: Models, Files and a Great First Prompt (Claude, 7 min)
- Give Examples: Few-Shot Prompts That Copy Your Style (ChatGPT, 6 min)
Frequently asked questions
- Which AI benchmark matters most?
- None for everyday office work. The best test is a few of your own tasks run on each model.
- Can AI companies game benchmarks?
- Scores can be inflated if test questions leak into training data or a model is tuned for the test, which is why newer benchmarks keep appearing.
- What does it mean when a benchmark is saturated?
- Top models all score near the maximum, so the test no longer shows which one is better.