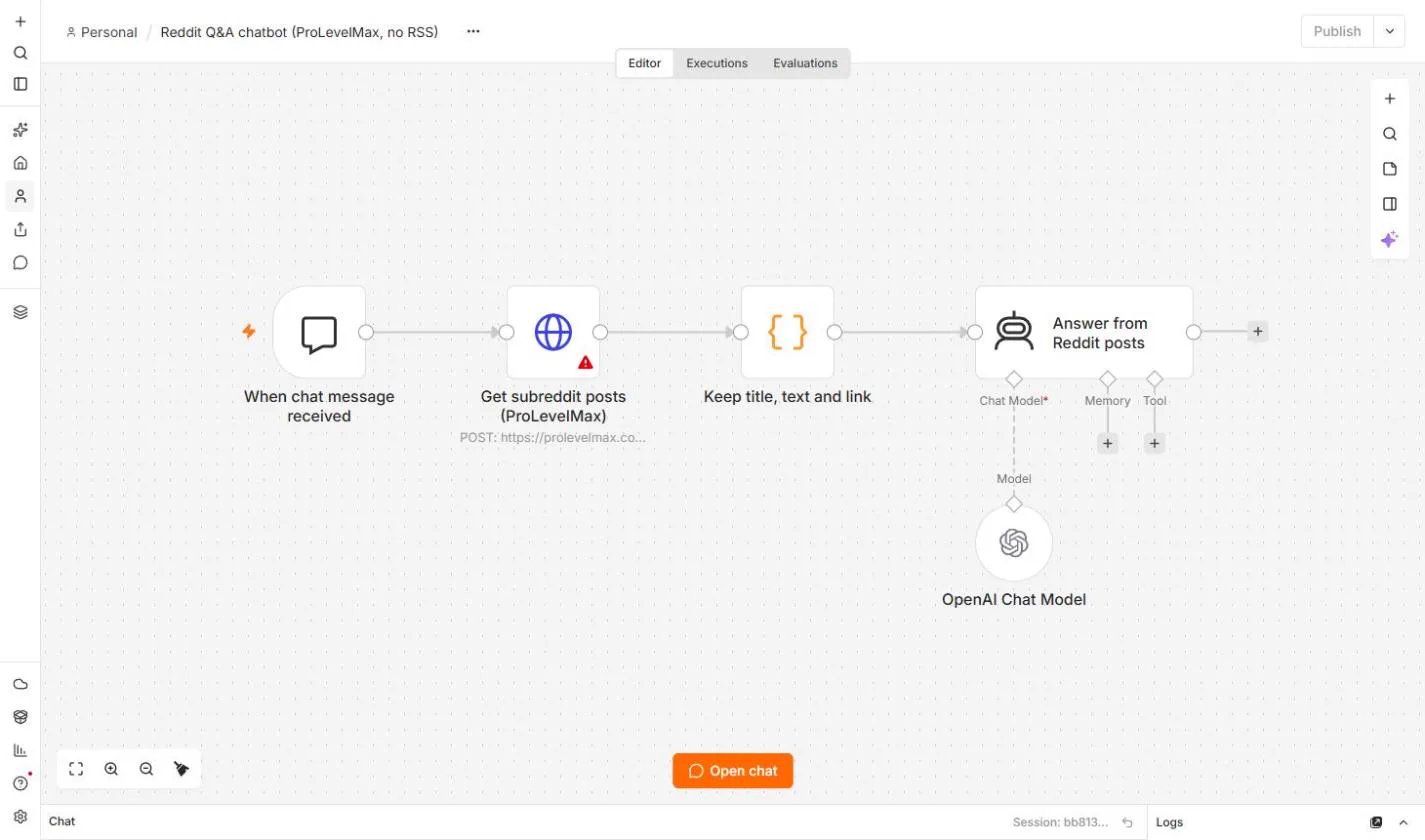
The example is the lesson's made-up company, Tallgrass Books. Its marketing manager, Maya Chen, gets a Slack summary of r/smallbusiness every morning. Reddit switches off its RSS feeds on November 13, so her RSS Read node is about to return nothing.
What are the most common ProLevelMax and n8n mistakes?
| # | Mistake | Fix |
|---|---|---|
| 1 | API key pasted into the URL or JSON body | Put it in a Bearer Auth credential |
| 2 | Method left on GET | Set Method to POST |
| 3 | A different URL for each source | Always https://prolevelmax.com/v1/run; the body picks the source |
| 4 | Guessed field names in the body | Copy them from the console's Collect form |
| 5 | Clicking Run in the console to test | Let n8n make the call; Run is a paid call too |
| 6 | Later nodes still reading title and link | Read post.postTitle, post.url and the rest, or map them |
| 7 | Sending the AI every field | Trim the posts in a Code node first |
| 8 | Expecting comments from the feed | Add a second call to Post comments |
| 9 | Switching on November 13 | Switch now and run both side by side |
Where should the ProLevelMax API key go?
1. The key in the URL or the body. The lesson is firm on this one: keep the key out of the workflow itself, out of chats and out of emails. A key typed into the URL or the JSON ends up in exported workflows, screenshots and logs. In the HTTP Request node, set Authentication to Generic Credential Type, set Generic Auth Type to Bearer Auth, choose Create new credential and paste the key into Bearer Token. n8n stores it encrypted and adds an Authorization: Bearer header to every request. That header is how a bearer token works.
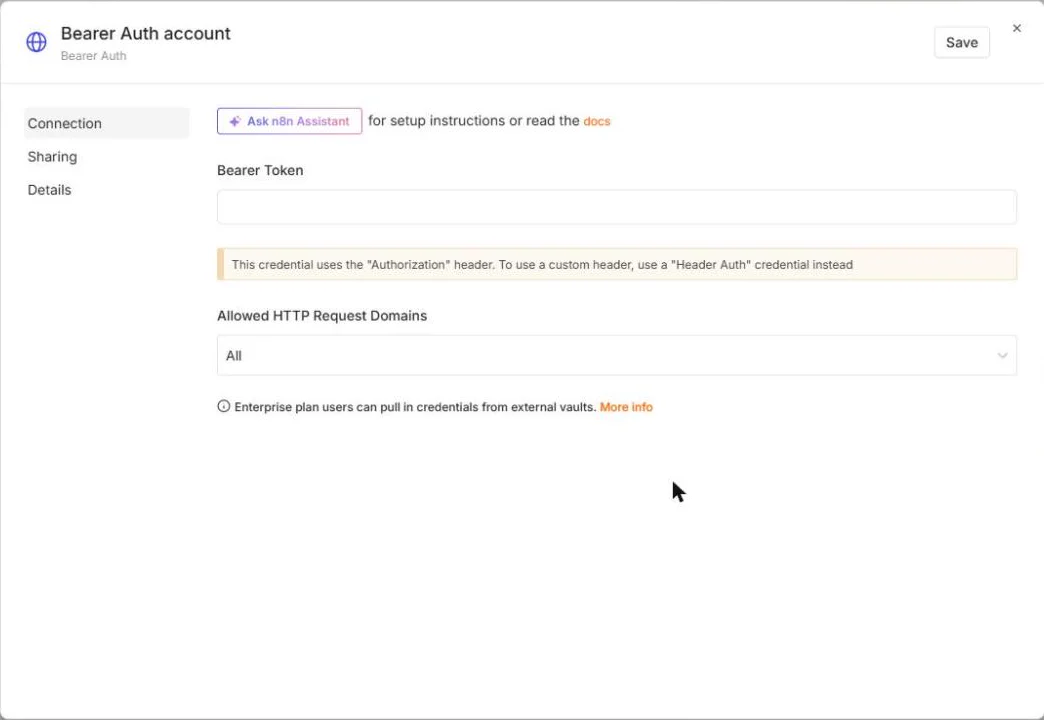
Make one credential named ProLevelMax and reuse it in every workflow that calls the API. If a key ever leaks, remove it under API keys in the console and create a new one.
Why does the HTTP Request node return an error?
2. GET instead of POST. A new HTTP Request node starts on GET. ProLevelMax needs POST, because you are sending it a small instruction (which source, which subreddit), not just reading a page.
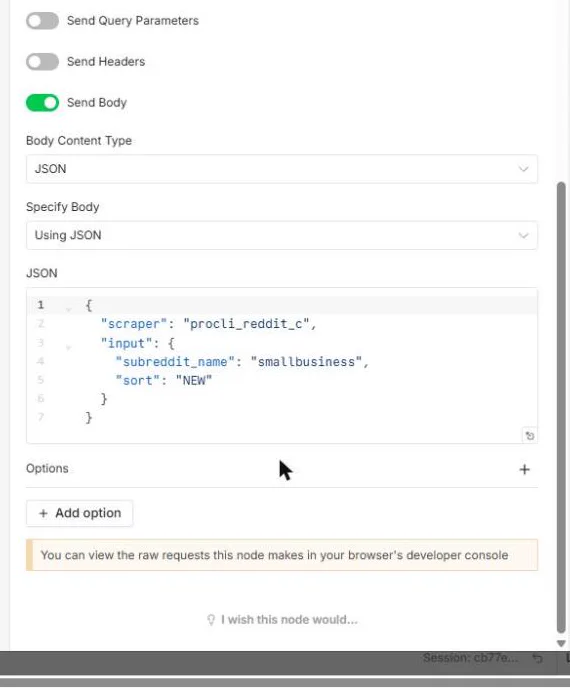
3. A new URL for every source. There is one API endpoint for every source: https://prolevelmax.com/v1/run. The scraper value in the body says which source runs. If you switch from the subreddit feed to post search, you change the body, not the URL.
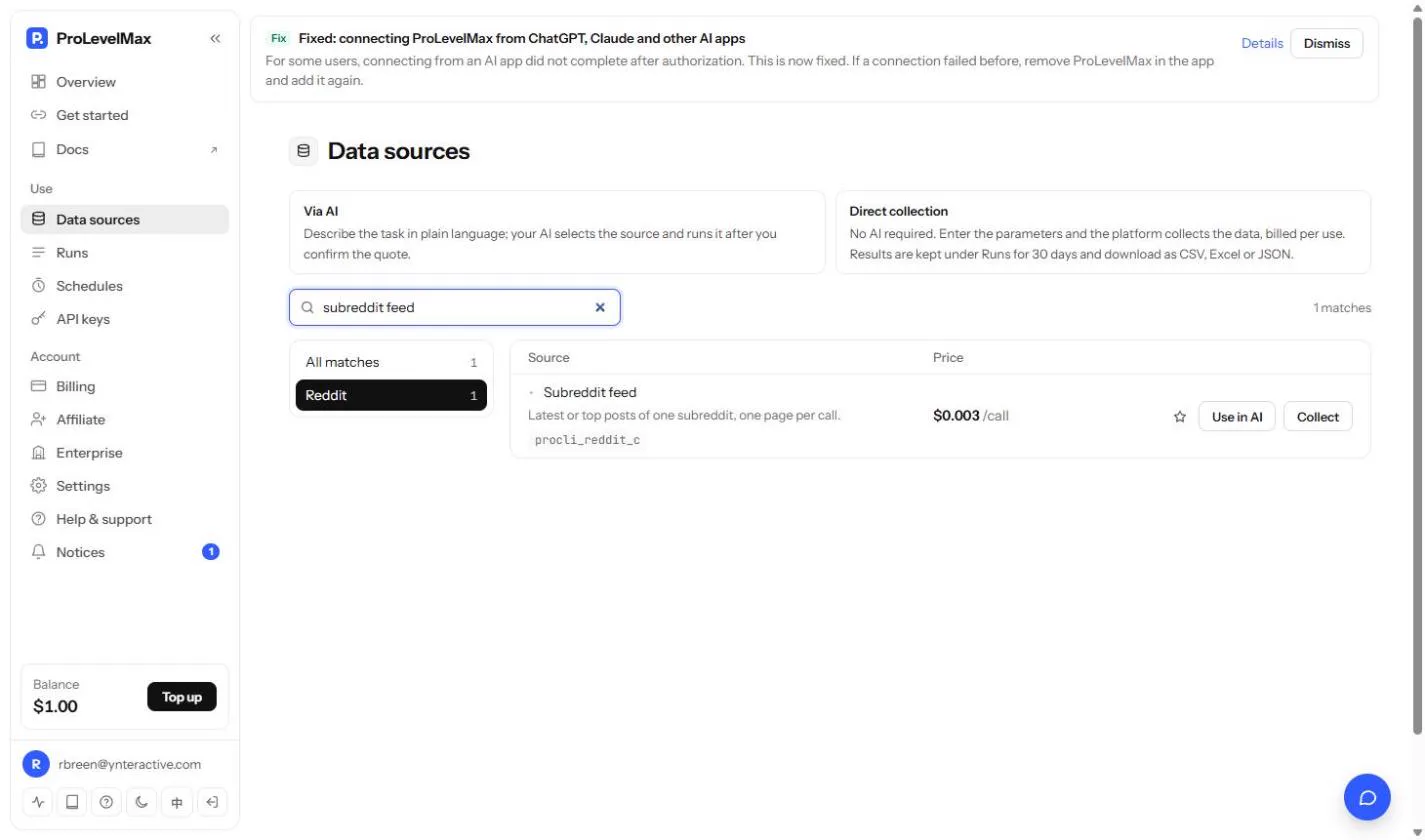
4. Field names that don't match. The body must use the exact names the source takes. For the Subreddit feed source (procli_reddit_c) those are subreddit_name, which is required, and sort, which takes BEST, HOT, NEW, TOP, CONTROVERSIAL or RISING. Don't guess: open Data sources, find the source and click Collect. The form shows the field names, and they are the same ones the API takes.
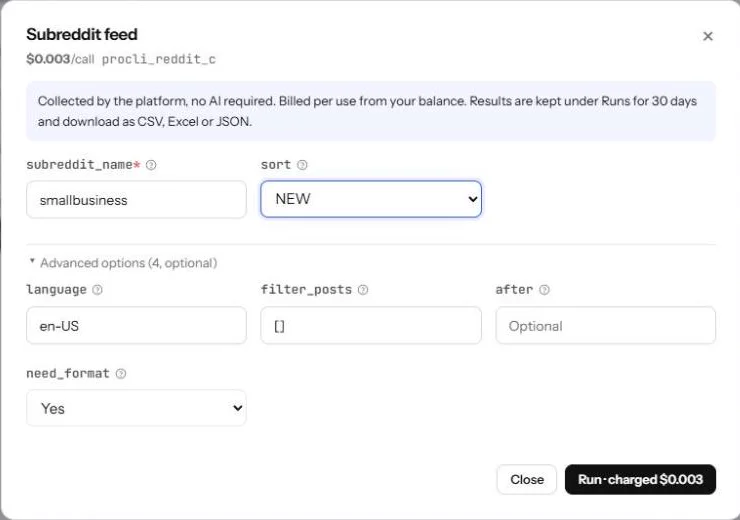
5. Testing with Run in the console. Run on the Collect form works, but it charges $0.003 and saves a result under Runs. You don't need it: close the form and let n8n make the call. One extra call won't hurt, but there is no reason to pay twice for every test.
Try it free, step by step
ProLevelMax in n8n: Keep Your Reddit Workflow Alive After the RSS Shutdown. Reddit switches off its RSS feeds on November 13. Swap the RSS Read node in your n8n workflow for one HTTP Request node that pulls the newest subreddit posts from ProLevelMax, then let AI sum up… You do every step yourself in a practice copy of n8n, it checks your work as you go, and “Do it for me” finishes any step you get stuck on. Free, and nothing touches your real accounts.
Start the free lessonWhy are the nodes after it empty?
6. Reading the old RSS field names. An RSS Read node hands on title, link and friends. ProLevelMax puts each post's fields inside a post object: post.postTitle, post.url, post.createdAt, post.score and post.commentCount, and the posts themselves arrive in items. If your Slack or Sheets node still asks for {{ $json.title }}, it finds nothing. Either update those expressions, or do what the keyword monitor workflow does: split items into one item per post, then map each field back to its RSS-style name in an Edit Fields node. The keyword monitor template has that mapping ready.
What goes wrong with the AI step?
7. Sending the AI every field. The response carries more than you need. The lesson puts a small Code node between the request and the AI Agent that keeps the title, text, score, comment count and link for each post. The AI reads a short, tidy list, which is cheaper and easier for it to summarize. A small model such as gpt-4o-mini is enough for this.
Two more AI slips are worth naming. The system message should tell the agent to answer using only the Reddit posts provided, group what people say into 3 to 5 themes, quote short bits with the post links, and say so when the posts don't cover the question. Without that last line, a model fills gaps with guesses. And don't trust the summary blindly: open a couple of the linked posts before you act on a theme. That habit is what turns a Reddit feed into real social listening.
8. Expecting comment threads. The subreddit feed returns posts, one page per call. Comment threads come from a different source, Post comments (procli_reddit_b), at $0.003 per call. Add it as a second call for only the posts you care about.
When should I switch from RSS?
9. Waiting for the deadline. Reddit announced the November 13 shutdown on r/modnews on September 30. Build the ProLevelMax branch now and run it next to the RSS Read node for a few days, so you can compare what each returns while both still work. One call a day costs about 9 cents a month at $0.003 per call, and new users get $1 of free credit after verifying their email. Check the ProLevelMax entry in the AI tools directory and prolevelmax.com/pricing for current prices.
Key takeaways
- Keep the ProLevelMax key in a Bearer Auth credential, never in the URL, the body or a screenshot.
- POST to one URL,
/v1/run, and let the body'sscrapervalue pick the source. - Copy field names from the console's Collect form instead of guessing.
- Post fields live under
post.; map them if later nodes expect RSS names. - Trim posts before the AI step, tell it to answer only from the posts, and spot-check the links.
- The one-page ProLevelMax cheat sheet has every setting in one place.
Frequently asked questions
- Why does my ProLevelMax request fail with an authorization error?
The key is missing or in the wrong place. Use Generic Credential Type, then Bearer Auth, and paste the key into Bearer Token in a saved credential.
- Do I need a different URL for comments or search?
No. Every source uses
https://prolevelmax.com/v1/run. Change thescraperid in the body, for exampleprocli_reddit_bfor post comments.- Is clicking Run in the ProLevelMax console free?
No. It charges the same $0.003 as a call from n8n and saves the result under Runs. You can skip it and test from n8n.
- Why do my Slack messages show blank titles?
Your Slack node is reading
title. ProLevelMax returnspost.postTitle. Change the expression or add a mapping step.- Can I keep my existing AI and Slack nodes?
Yes. Only the RSS Read node is replaced. For more answers, see the ProLevelMax Reddit API FAQ.