What is training data in AI?
Updated · By Robert Breen
Training data is the large collection of examples, such as text, images or labeled records, that an AI model learned from before you ever used it. The model's knowledge, writing habits and blind spots all come from that data, which is why it knows general things but not your business.
Why it matters for a small business
Training data explains why AI out of the box sounds the way it does. A model trained on huge amounts of public writing has absorbed the average marketing post, the average customer email and the average estimate. Ask it with no context and you get that average back. Your brand voice, prices and policies were never in its training data, so you have to supply them.
It also matters for privacy. Some AI services may use your conversations to train future models, depending on the plan and settings. If you paste client details into a tool that trains on chats, those details could become part of a future training set. Checking how your plan handles this is part of using AI responsibly at work.
In a real lesson: Build a Custom GPT Social Media Assistant
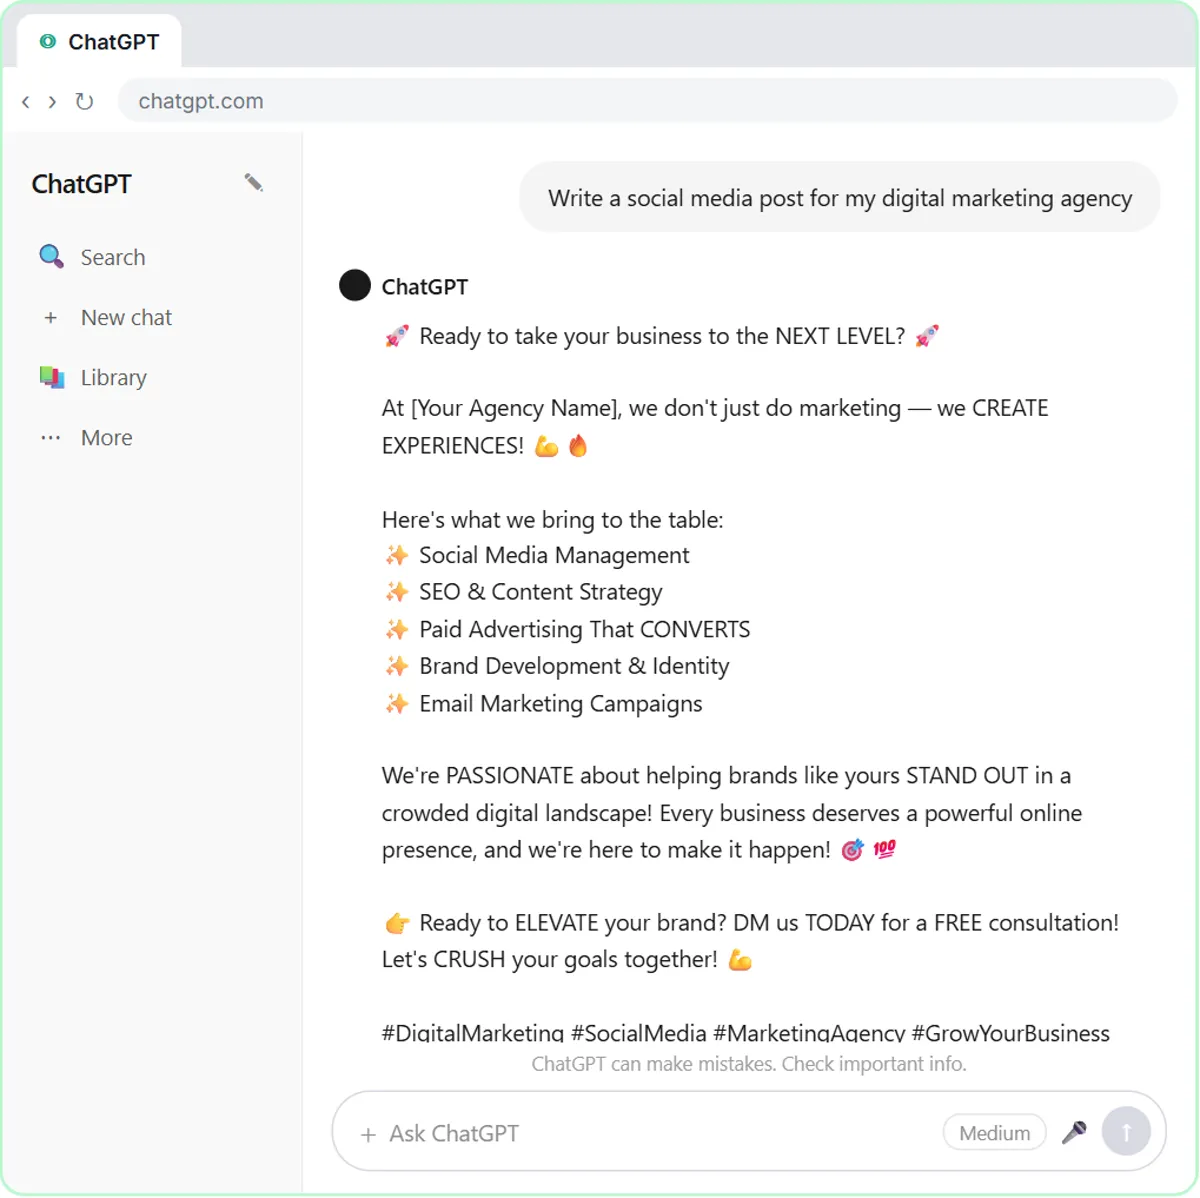
The Custom GPT social media lesson shows training data at work. You start by sending ChatGPT a bare prompt: "Write a social media post for my digital marketing agency." The reply is full of emojis, hashtag spam and words like elevate and crush. The voice-over notes it sounds like every other marketing post on the internet, which is exactly what you would expect from a model that learned from lots of them.
Then you build a Custom GPT called Social Media Assistant. You paste instructions that ban emojis and words like synergy, leverage and elevate, cap posts at 150 words and allow two hashtags at most, and you use Upload files to attach Ynteractive-Brand-Voice.pdf.
Sending the same prompt again gives a very different post. The model's training data did not change; you added the specific material it never had. That is the general pattern: training data gives the model language skill, and your instructions and files give it your business.
Try this lesson free or read the step-by-step guide.
Common confusions
Training data vs knowledge files
Training data shaped the model before release and cannot be edited by you. A file uploaded to a Custom GPT is reference material it consults when answering. Uploading a file does not retrain the model; see fine-tuning for the kind of training that does.
Training data vs the information in your prompt
What you paste into a chat is input for that conversation. It only becomes training data if the service is allowed to use your chats for training under your plan and settings.
Tips
- When AI output feels generic, assume the model is falling back on its training data and give it your own examples and facts.
- Before pasting client information, check whether your plan uses chats for training and turn that off or use a business plan if needed.
Related terms
Where you use it: free lessons
- Build a Custom GPT Social Media Assistant (ChatGPT, 8 min)
- Turn an Interview Debrief into a Scorecard and a Candidate Follow-Up (Recruiting & HR) (ChatGPT, 9 min)
Prompt templates that use it
Frequently asked questions
- Does ChatGPT train on what I type?
- It depends on your plan and settings. OpenAI provides data controls that let you opt out of training on your chats, and it says business plans are not used for training by default. Check the current settings for your account.
- Can I add my business to an AI model's training data?
- Not to a model like the one behind ChatGPT. You can give it your information through prompts, Custom GPT instructions and uploaded files, which works without retraining anything.