What is inference in AI?
Quick answer
Inference is the moment a trained AI model takes your input and produces an output, such as a reply, a category or a row of extracted data. Training builds the model once; inference is every time you use it, and it is what API usage bills are mostly made of.
Last updated
Updated · By Robert Breen
Why it matters for a small business
When you hear that AI is expensive or slow, the cost usually comes from inference: each request uses computing power, measured in tokens in and out. A small model answering a short question costs very little. A large model reading a long document, or an agent making several calls per task, costs more and takes longer.
Knowing this helps you make sensible choices. You pick the model for each job, set how much text goes in, and decide how often a workflow runs. An email agent that calls the model once per new message costs more in a busy week than a quiet one. Those choices, more than the model's brand, shape your monthly bill.
In a real lesson: n8n AI Agent Tutorial: Save Social Media Ideas to Google Sheets
The n8n AI agent lesson puts inference costs in front of you early. Building an agent for BrightPath Marketing, a made-up agency, you add funds to an OpenAI account, and the narration explains that "Ten dollars goes a very long way. You are charged per request, not per month." Each request is an inference call.
When you pick the model, the lesson chooses gpt-5-mini: "Fast, cheap, and plenty for generating social media ideas. Do not reach for the expensive model until you have a reason." That is an inference decision. A smaller model means quicker, cheaper answers, which is enough for three post ideas.
Then watch what one chat turn involves. When you ask for 3 post ideas, the model reads the system message, the conversation from memory and your request, then writes its reply. When you say Yes, save those ideas to the sheet, it runs again to decide on the Sheets tool and fill each column. The same thing happens in the AI Receipt Extractor lesson, where each receipt photo you drop in is another inference run.
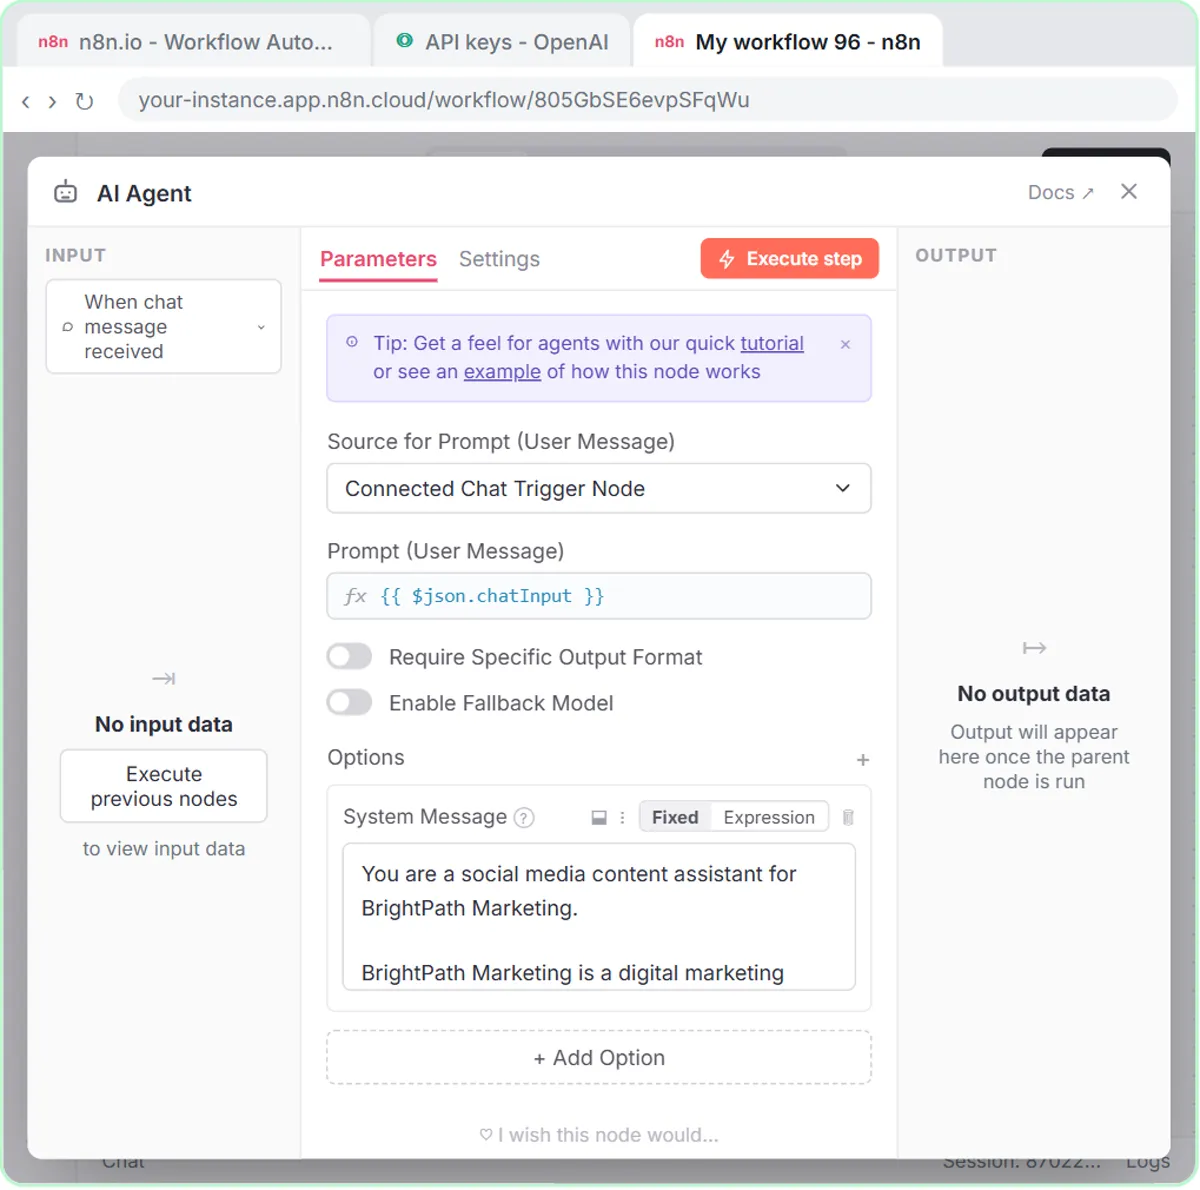
Try this lesson free or read the step-by-step guide.
Common confusions
Inference vs training
Training is how a model learns from huge amounts of data, done by the model maker. Inference is using the finished model. When you use ChatGPT or an n8n agent, you are only doing inference.
Inference vs reasoning
A reasoning model spends extra effort working through a problem before it answers. That extra work is still inference, so it usually costs more per request and takes longer.
Tips
- Start with a small, fast model and move up only when results are not good enough.
- Send only the text the task needs. Long pasted documents raise the cost of every call.
- Set a monthly spending limit in your AI provider's billing settings.
Related terms
More AI basics terms
Where you use it: free lessons
- n8n AI Agent Tutorial: Save Social Media Ideas to Google Sheets (n8n, 12 min)
- AI Receipt Extractor: Receipts to Google Sheets with n8n (n8n, 12 min)
- Build an AI Agent That Categorizes Business Expenses (n8n, 12 min)
Frequently asked questions
- Why do providers charge per token?
- Tokens roughly track how much computing work each request takes, both reading your input and writing the output. Check your provider's pricing page for current rates.
- Can I run inference on my own computer?
- Yes, with smaller open-weight models and the right software, though they are usually less capable than large hosted models. Most small teams use a hosted service.